SortSpoke for Loss Run Reports
Turn any carrier's loss runs into clean, verified claims data
Every field extracted from a loss run traces back to the source document and the person who reviewed it — bring your own loss runs and see live results, not a canned demo.
SortSpoke is insurance document AI: we turn submissions, loss runs, and the rest of your document intake into verified data — inside the systems your team already works in.
- Extract carrier, claim, and loss details from any loss run format
- Eliminate manual data entry from scanned PDFs, spreadsheets, and multi-carrier documents
- Prioritize high-potential submissions with enriched, structured data
- Every value verified by your reviewers and traceable to its exact spot in the source PDF
Four ways to solve loss run data extraction
If you're evaluating how to get clean claims data out of loss runs, you're weighing the same four options as every underwriting team. Here's the honest comparison.
1. Keep it manual
Underwriters or assistants rekey claims data line by line. Accurate on any format — but it doesn't scale. A multi-carrier loss run takes hours, and industry estimates put up to 40% of underwriters' time on administrative work.
2. Send it to a vendor's review pool
A human-powered service keys the data for you. It works — but the vendor's staff sit in your critical path: throughput depends on their headcount and shift coverage, turnaround is measured in hours or days, and cost scales with people rather than documents.
3. Point a generic tool at it
Generic document AI — or a DIY LLM pipeline — handles clean, consistent forms well, then breaks on the messy reality of multi-carrier loss run formats. And when it's wrong, nothing governs, verifies, or traces the output.
4. Automation-first AI
Straight-through platforms route only what the model itself flags as low-confidence to review. A confidently-wrong extraction never surfaces — you find it at renewal, or in an audit.
SortSpoke's approach: governed extraction
AI does the extraction. Your people — and only your people — verify it. You set the confidence thresholds that decide what gets reviewed, and every field traces back to its exact place in the source document. Accuracy is governed, not promised.
SortSpoke processes loss runs without per-carrier templates. Pretrained loss run models and template-free extraction read each carrier's layout as it arrives, so a new carrier format needs no template setup. Zero-configuration OCR and handwriting recognition handle scanned, faxed, photographed, and handwritten loss runs, and claims in different layouts are captured as consistent structured records.
How SortSpoke is different
Built for underwriting teams that need the speed of AI and the accountability of their own reviewers.
You set the confidence thresholds
Every extracted field either clears the confidence bar you set or goes to your reviewers. What gets human review is governed by your rules — not by the model's opinion of itself.
Every value traces to its source
Click any extracted value to see exactly where it came from in the source PDF — with an audit trail of who reviewed it, what changed, and when. Your underwriters don't have to trust the AI; they can check it.
Inside the systems you already run
SortSpoke is one of the few extraction platforms built to run inside your underwriting workbench, intake inbox, or policy admin system. What lands in your system of record is verified data your team can check — not a recommendation you have to trust.
A product, not a service
There's no vendor review pool behind the curtain. Cost scales with documents, not people, and your throughput never depends on anyone else's headcount or shift coverage. The only humans in the loop are yours.
How It Works
Extract Data Quickly
From messy, multi-carrier loss runs to clean claims data — here’s the pipeline.
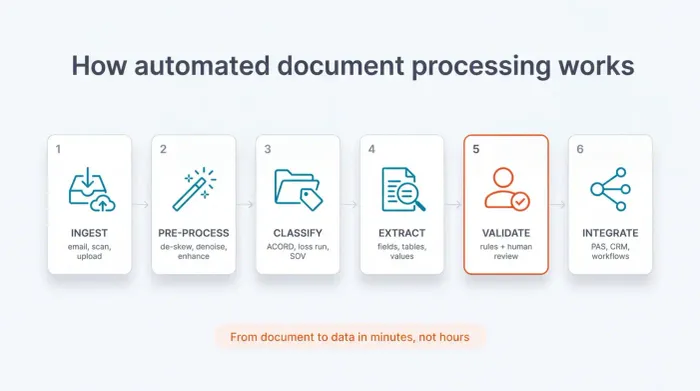
Embedded in the tools your team already uses
SortSpoke isn't another portal. Loss run extraction and underwriter review run inside your existing underwriting workbench, intake inbox, or policy admin system — so adoption doesn't depend on changing how your team works.
AI extracts and standardizes the claims data; your underwriters review and approve without leaving the tools they know. The clean loss data lands in your system of record, ready for risk assessment.

Eliminate the Loss Run Bottleneck
5X
Process loss run submissions 5X faster — Great American.
>95%
Extraction accuracy on real-world loss runs, measured on production data — and every field either clears the confidence threshold you set or your reviewers make the call.
30m
Live in 30 minutes. Go from sign-up to extracting your first loss runs in under half an hour.
Customer Reviews
What SortSpoke Customers Say

P&C Manager
SORTSPOKE CUSTOMER
Manager, Global Digital Underwriting
RGA International
VP Underwriting Business Solutions
RGA
Assistant VP of Analytics
SORTSPOKE CUSTOMER
Assistant VP of Analytics
Sortspoke customer
SortSpoke Platform | Security
Built for Enterprise
At SortSpoke, we understand that document processing in insurance and financial services demands the highest levels of security and compliance. Your sensitive data never leaves your control.
Our Security Foundation:
SOC 2 Type II compliant infrastructure built on AWS
Role-based access controls
Comprehensive audit logging and monitoring
By clicking Book Now you're confirming that you agree with our Terms and Conditions.
See your loss runs processed 5X faster
Enter your email and go straight to the calendar — pick a demo time that works for you. Then bring your messiest loss runs and watch the extraction live.
What is a loss run?
Quick reference: what a loss run is, what one contains, and how to read it.
Definition
A loss run is a report issued by an insurance carrier that lists a policyholder's claims history over a set period — typically three to five years.
Each entry records the claim date, type, status, amount paid, and reserves. Underwriters use loss runs to assess risk and price renewals. Every carrier formats them differently, which is what makes them slow to process at scale.

What is in a loss run report?
A loss run report typically contains the policy number and effective dates, a line per claim with date of loss and claim status (open, closed, or reopened), amounts paid, outstanding reserves, and a total incurred figure. Carriers vary in whether they include claimant detail, cause-of-loss coding, and subrogation recovery.
How far back does a loss run report go?
Most submissions ask for three to five years of loss history. A 5 year loss run report is standard for commercial lines; a 3 year loss run report is common for smaller accounts.
How do you read a loss run report?
Read a loss run by first checking the policy period and whether the report is valued to a recent date. Then review each claim line for status, paid amount, and reserves. Total incurred is paid plus reserves. Open claims with large reserves carry the most forward-looking risk.
How long does manual loss run review take?
Industry estimates put up to 40% of underwriters' time on administrative work — much of it manual document handling like loss run processing. At 1,000 submissions a month, that's roughly 500–1,000 hours of underwriter time on loss run processing alone — time an automated extraction workflow gives back to risk assessment.


